A BI dashboard that takes 45 seconds to load changes how people use data. Executives refresh the page, wait, and then ask whether the numbers are ready. Analysts open extra tabs, rerun similar queries, and consume more warehouse capacity while the original bottleneck remains untouched.
Snowflake query optimization works best when you treat performance as an investigation, not a guessing exercise. The largest gains often come from data layout, micro-partition pruning, query shape, and recurring workload patterns, rather than assigning a larger warehouse. Snowflake's own benchmark program reports a 40% average improvement in stable workload query duration since August 2022, which shows that systematic tuning can deliver measurable results at scale. (Snowflake performance guidance)
The outcome is practical: faster dashboards, more predictable applications, lower unnecessary compute consumption, and fewer frustrated users. The process starts with a baseline, identifies the actual bottleneck, applies one targeted change, and measures the result.
Why Your Snowflake Queries Are Slower Than They Should Be
The slow dashboard usually isn't caused by one dramatic mistake. A report may combine a broad date range, several joins, calculated fields, and application-generated filters. Each part can look reasonable in isolation, while the complete query scans far more data than the user's question requires.
Traditional database tuning often centers on indexes, lock contention, and server memory. Snowflake uses a different performance model. Its tables are organized into immutable micro-partitions, and the engine relies heavily on metadata, pruning, columnar scanning, and elastic compute. That makes data organization and predicate design more important than blindly adding an index or increasing warehouse size. (Snowflake micro-partition documentation)
A useful first question is not, “Which warehouse should we use?” It's, “How much data did this query need to touch to answer the question?” If the query scans almost every available micro-partition, more compute may reduce elapsed time temporarily, but it won't correct poor pruning. If operators spill data to storage or a join produces far more rows than expected, warehouse expansion can hide the symptom while increasing consumption.
Practical rule: Measure the query before changing the warehouse. A larger warehouse is a capacity decision, not a substitute for fixing query shape or data layout.
The practitioner mindset is straightforward:
- Start with outcomes: Track dashboard responsiveness, application latency, workload predictability, and credit consumption.
- Find the bottleneck: Separate scan volume, memory pressure, joins, aggregation, and result delivery.
- Change one variable: A single rewrite or layout adjustment makes the performance delta easier to interpret.
- Keep the baseline: Preserve the original profile so later improvements can be compared against the same evidence.
Snowflake query optimization isn't about making every SQL statement elegant. It's about making the workload do less unnecessary work, then proving that the change improved the behavior users experience.
Reading Query Profiles to Pinpoint the Bottleneck
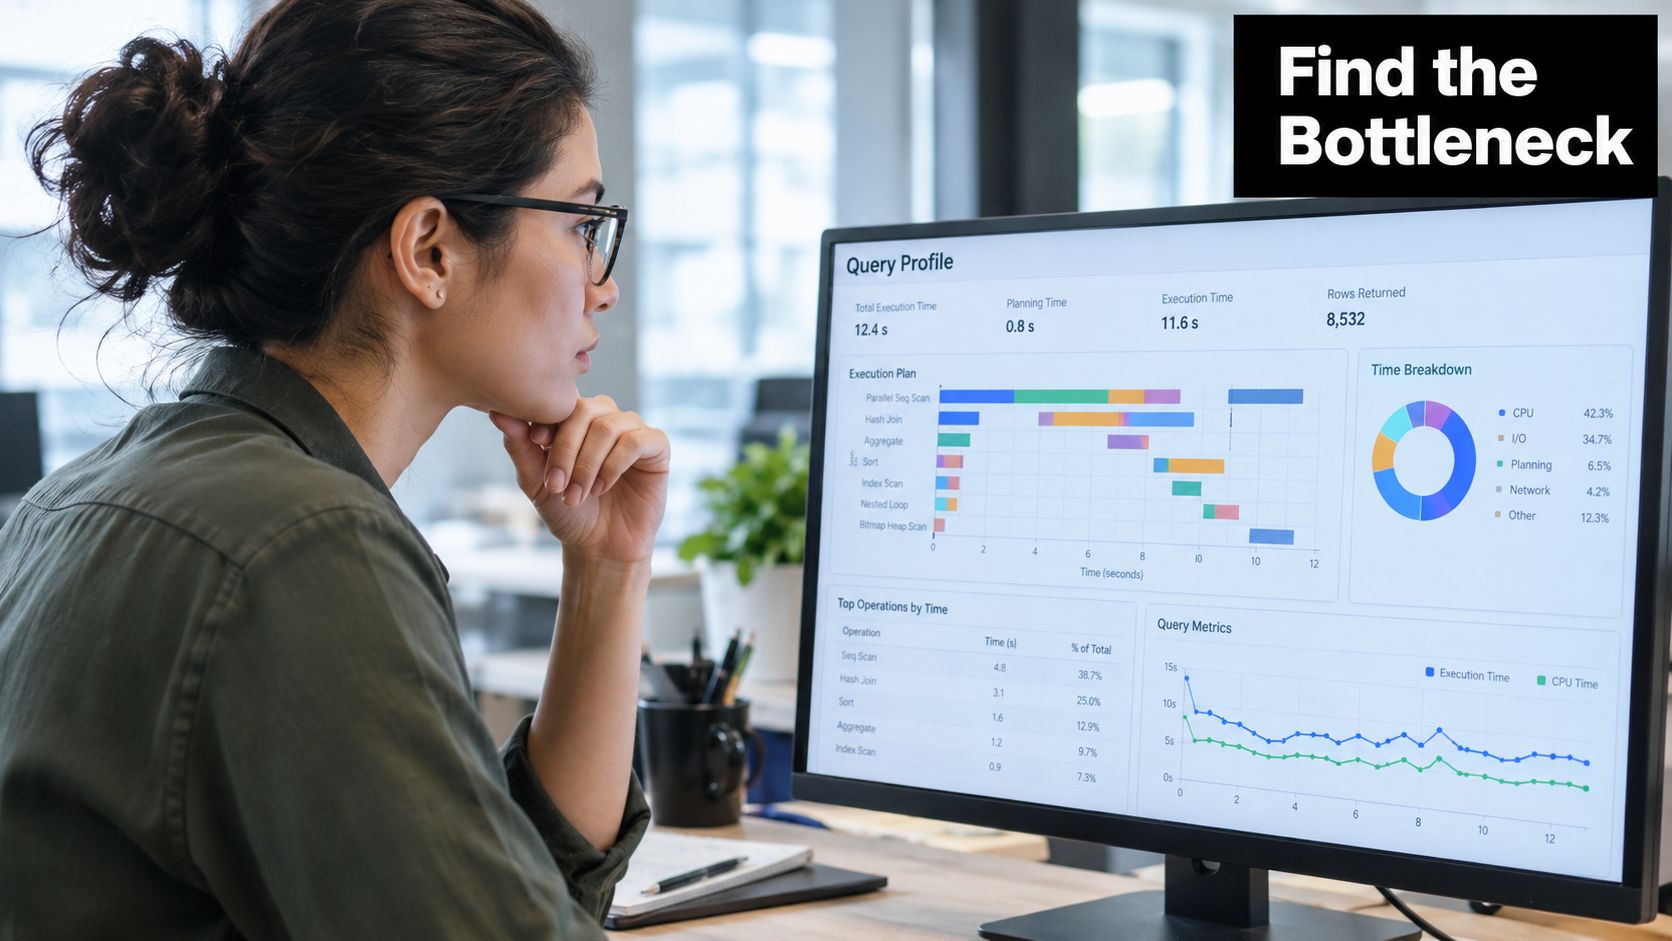
A dashboard query can feel slow even when its SQL looks reasonable. Open the Snowsight query profile before rewriting anything. Start with total execution time, then locate where that time accumulates across scans, joins, aggregations, sorts, and data movement. Operator-level evidence matters because total duration alone rarely identifies the work responsible for the delay.
Establish a query-level baseline
Record execution duration, partitions scanned versus partitions total, bytes spilled to storage, and row counts entering and leaving major operators. Compare those measures before and after each change. (Snowflake query performance guide)
Partition counts usually provide the quickest direction. If the query scans only a small share of available micro-partitions, inspect joins, sorting, aggregation, or memory pressure. If scanned partitions remain close to the total, investigate pruning, particularly when the predicate should be selective.
A useful baseline also captures the query shape and workload conditions. Keep the original profile, warehouse context, and representative parameters so later comparisons reflect the same request rather than an unrelated run. This evidence supports workload-adaptive tuning in 2026: repeated patterns become easier to recognize, and SQL changes can be judged by how consistently they reduce work across the workload.
Separate the three common failure modes
Spill-to-storage indicates memory pressure. Find operators writing intermediate data outside memory, commonly joins, aggregations, and sorts. Before increasing warehouse capacity, remove unused columns, reduce oversized intermediate results, and apply selective filters before expensive operations.
A high partition-scan ratio indicates that Snowflake cannot eliminate enough micro-partitions. Review filter columns, value distribution, and expressions that may prevent useful metadata comparisons. Snowflake's performance guidance explains pruning through the relationship between unscanned and total micro-partitions, using minimum and maximum metadata for columns in filters or join keys. (Snowflake pruning guidance)
Join explosions appear as unexpectedly large intermediate results. Check join keys, row counts on both sides, duplicate grain, and predicates applied before the join. A Cartesian product or many-to-many relationship can dominate the profile even when individual table scans look acceptable.
Make one change, then measure
Use an iterative loop:
- Capture the baseline in Snowsight or the query profile.
- Identify the dominant operator and its supporting metric.
- Apply one targeted fix, such as pushing a selective filter earlier or correcting a join condition.
- Run the same workload under comparable conditions.
- Compare the delta in duration, scan volume, spills, and operator statistics.
Warehouse scaling can produce an immediate improvement, but it may conceal the underlying issue. If partition scans remain high, the query still reads too much data. If spills disappear but join output remains excessive, memory was only part of the problem.
Review the second profile with one concrete question: did the bottleneck move, shrink, or remain unchanged? That answer is more useful than saying the query merely felt faster. Repeated profile comparisons give the optimizer and the engineering team a clearer pattern to act on than isolated manual rewrites.
Micro-Partition Pruning and Clustering Keys That Work
Snowflake performance often depends on whether the engine can discard data before reading it. Tables are stored in immutable micro-partitions, with metadata such as minimum and maximum values for columns. If a predicate cannot match a partition's metadata range, Snowflake can skip that partition entirely. The same approach can support pruning for semi-structured columns when the filter matches the available metadata. (Snowflake clustering and micro-partition documentation)
Read scan volume before changing clustering
Start with the query profile. Compare partitions scanned with partitions total to see whether pruning is doing useful work. A small scanned-to-total ratio indicates effective pruning. A ratio close to the total suggests that the predicate does not match the way values are organized, the filter is not selective enough, or a transformation has weakened metadata-based elimination.
Clustering depth provides a second diagnostic. In common practitioner workflows, lower clustering depth is better, and a perfectly clustered table approaches 1.0. That value does not guarantee faster queries. It describes how closely physical organization follows the selected clustering dimensions. The workload still determines whether those dimensions reduce meaningful work. (Practitioner analysis of Snowflake performance optimization)
A time-series table filtered repeatedly by event date and tenant is a strong clustering candidate when those predicates are selective. A table filtered mainly by a nonselective status value may gain little, because many partitions can still contain matching rows. Frequent rewrites can also reduce the benefit of clustering while adding maintenance work.
Match the key to the workload
Choose clustering columns from observed filters and join keys, rather than from the schema alone. A column that looks important for analysis may not improve the dashboards and recurring queries that consume the warehouse.
Consider a large event table where queries select one tenant and a narrow time interval. Poor organization can force a query to scan hundreds of thousands of micro-partitions. In documented cases, aligning the clustering key with the tenant and event-date filter reduced that scan to only a handful of micro-partitions. The result changed the response from a minutes-level scan to seconds-level execution. Snowflake's documentation on clustering depth metrics and table organization explains the physical signals behind this evaluation.
Those results depend on selectivity and data organization. Clustering will not fix a join at the wrong grain, a filter applied after a row-expanding operation, or a query that needs most of the table. It is not economical for every table either. Compare repeated workload duration and scan volume with the background maintenance needed to preserve the layout.
A practical review asks:
- Does the workload repeatedly filter on the proposed key?
- Do those filters eliminate a meaningful portion of partitions?
- Is the table rewritten often enough to increase maintenance overhead?
- Do joins use compatible keys and sensible grain?
- Does the profile improve after the change?
The Snowflake time-series data success story offers additional context for evaluating organization in time-oriented workloads.
In 2026, the useful shift is from treating clustering as a one-time manual rewrite to designing recurring workloads with stable, observable access patterns. Consistent tenant and event-date predicates give Snowflake a clearer basis for adapting to repeated behavior. A low clustering-depth reading still matters only when it reduces work for important queries. If it does not, the maintenance cost has no practical justification.
Choosing the Right Acceleration Feature for Your Workload
Snowflake gives teams several ways to accelerate queries, but they solve different problems. The right choice depends on query shape, data volume, freshness requirements, and repeated usage, not on which feature sounds most powerful.
FeatureBest ForData VolumeCost ConsiderationSearch Optimization Service and Optima IndexingPoint lookups and substring filters on structured dataLarge tables with selective access patternsMeasure recurring latency gains against service and background maintenance consumptionQuery Acceleration ServiceAd-hoc analytics that occasionally needs extra processing capacityMassive scans or uneven workloadsUseful for bursts, but validate that acceleration reduces user-facing latency enough to justify creditsClusteringRepeated selective filters, especially time-series accessTables where physical organization can reduce partition scansMaintenance can outweigh gains when filters aren't selective or data is frequently rewrittenMaterialized viewsRecurring aggregations and stable transformationsRepeated summaries over substantial source dataRefresh work and freshness requirements must fit the business need
Search optimization for selective access
Search Optimization Service is a natural candidate for point lookups and substring filters where ordinary pruning can't eliminate enough data. Snowflake's 2025 and 2026 releases expanded search optimization and Optima Indexing, including automatic background index maintenance, and Snowflake's January 2026 release notes describe improvements for point lookup and substring queries on structured data. (Snowflake performance options)
The economic test is simple: identify the recurring query family, measure its baseline duration and scan behavior, then compare the resulting user or application benefit with the additional consumption. A feature that accelerates an occasional query may not justify ongoing maintenance.
Acceleration for uneven analytical demand
Query Acceleration Service fits workloads where a small number of ad-hoc queries occasionally require more processing than the normal warehouse pattern provides. It can be preferable to sizing the entire workload for its largest outliers, but teams should verify that the accelerated queries are important enough to warrant the extra resource usage.
Materialized views are a different tradeoff. They work well when dashboards repeatedly calculate the same aggregation and can tolerate the view's freshness behavior. They're less attractive when users apply highly variable filters or when the underlying data changes in ways that make refresh work expensive.
Clustering remains a workload-specific layout choice, particularly for selective time-series filters. None of these features should be enabled as a default response to slow SQL. Build a small decision record for each candidate, including query frequency, baseline scan volume, latency target, freshness expectation, and measured resource impact.
Designing SQL for Workload-Adaptive Optimization
A dashboard can run the same business query thousands of times while changing only filter values. An application can generate equivalent SQL with different whitespace, casts, selected columns, or optional predicates. In 2026, optimization increasingly depends on designing these recurring workloads so Snowflake can recognize their patterns, rather than tuning each statement in isolation.
Snowflake Optima Planning reuses execution feedback across structurally similar queries, not only exact text matches, and applies dynamic sampling to improve selectivity estimates. (Snowflake 2026 performance improvements) That makes SQL shape an operational concern. If every generated statement looks unrelated, the engine has fewer consistent patterns to work from, and engineers also have a harder time grouping executions in query history.
Preserve recognizable query structure
Use parameterized queries when the client and access pattern support them. Keep the primary filter structure stable, and avoid unnecessary transformations around commonly filtered columns. Consistent structure gives the optimizer related executions to compare and gives engineers cleaner workload groups for review.
Do not force legitimate business variation into one rigid template. Optional logic will change some statements. Separate meaningful variation from accidental variation, such as inconsistent casting, redundant nested queries, or application code that expresses equivalent predicates in several forms.
BI teams should define shared semantic filters consistently across dashboards. Application teams should centralize query construction for high-volume access paths instead of letting each service produce its own version of the same request. Keep joins at the intended grain, and apply selective predicates as early as the logic permits.
Design principle: Write recurring SQL so the engine can recognize recurring intent, not just recurring text.
Snowflake reports up to 1.8x faster core analytics in its 2026 SQL performance improvements. That result supports a practical conclusion: engine-level adaptation now contributes to query speed, so a rewrite-only strategy forfeits gains the engine can deliver on its own.
Manual tuning still matters when a profile exposes a clear flaw. Evaluate whether a change fixes one execution or improves an entire family of structurally similar statements. Consistent query naming, parameter handling, and SQL construction turn individual fixes into patterns the optimizer can use repeatedly, while reducing the maintenance burden of hand-tuning every variant.
Monitoring Performance at Scale
Optimization ends only when the team can detect regression. A query that performs well after a rewrite may slow later because data distribution changes, dashboard filters evolve, joins gain new members, or caching behavior changes.
Build monitoring around workload-level trends rather than a list of individual slow queries. Snowflake query history can support recurring reviews of duration, scan behavior, and resource consumption, while resource monitoring helps identify unexpected warehouse usage.
Track the signals that explain outcomes
- Duration trends: Watch recurring query families for week-over-week increases rather than reacting only to the worst single execution.
- Partition scan ratios: A ratio above 50% should trigger a pruning review, especially for queries expected to be selective.
- Cache hit rates: A drop below 70% can signal changing query text, changing data, or a workload that no longer benefits from cached results.
- Credit consumption: Group consumption by dashboard, service, warehouse, or workload so expensive patterns have an owner.
The thresholds above are operating triggers, not universal laws. A broad month-end report may legitimately scan much of a table, while a point lookup should usually prompt investigation when it does. Use the expected query shape to interpret the alert.
Snowflake's persisted query results cache expires after 24 hours, and identical reruns can return cached output instead of recomputing when the underlying data hasn't changed. (Snowflake persisted query results) A high cache hit rate can improve responsiveness, but it shouldn't conceal poor pruning or inefficient SQL. Track cache-assisted executions separately from uncached executions so the underlying query behavior remains visible.
Create a dashboard that combines query history with warehouse consumption, then alert on sustained changes rather than isolated spikes. Assign an owner to each critical workload and review the profile whenever a threshold is crossed.
Building a Systematic Optimization Workflow
A recurring dashboard query is slow every morning, yet ad hoc rewrites produce inconsistent results. Use a repeatable sequence: baseline, diagnose, target, measure, monitor. Start with recurring slow queries, inspect spill-to-storage, partition-scan ratios, and join behavior, then correct data layout or SQL shape before resizing the warehouse.
Make one change at a time. Compare execution time, scanned partitions, spills, and operator statistics with the original profile. If the relevant metric does not improve, revert the change and test another hypothesis. This preserves a clear link between an intervention and its outcome.
The benchmark gains cited earlier came from systematic tuning. Apply that discipline at the workload level, where recurring query patterns can guide SQL design and adaptive optimization instead of treating every execution as an isolated rewrite.
Use this review checklist:
- Baseline metrics: Duration, partitions scanned, partitions total, spills, and operator statistics.
- Bottleneck identification: Scan inefficiency, memory pressure, join behavior, or repeated computation.
- Targeted fix: SQL shape, data layout, clustering, acceleration, or workload-adaptive design.
- Measurement: Compare the same metrics after one change.
- Monitoring setup: Add workload-level alerts and assign ownership.
Teams that need help formalizing these reviews can consider collaborating with Faberwork as a Snowflake partner. For consumption control, pair query-level performance work with this guide to cutting your Snowflake bill.
Start with your five slowest recurring queries this week. Capture their profiles, record scan and spill metrics, identify one bottleneck per query, and test one targeted change before resizing any warehouse. The result is a defensible baseline and a practical view of where the workload wastes time and credits.


